Why run Ai locally (or start testing it locally)?
Once SMEs realise Ai is far more than just chat, they start with practical questions: “What could Ai automate in our business, how can we best leverage Ai, so we don’t fall behind, what is it going to cost and what do we need to do first?”
Running Ai locally is a safe, low-drama way to learn and get started, without wiring public AI directly into sensitive systems before you’ve built confidence, policies, and good data hygiene.
The simple idea
Local AI = your data stays in your environment.
You can experiment with Ai assistants, document search (RAG), and workflow automations using your own files and internal knowledge, while keeping privacy, access control, and data cleanliness under your control. Mistakes seldom expose your data, take down your systems or cost £10000s in token use, if your Ai is local.
Key benefits
1) Better privacy and data hygiene
If you’re testing Ai on customer emails, pricing docs, contracts, HR policies, or internal playbooks, “local-first” means:
- Your private documents don’t have to be sent to third parties to get useful results.
- You reduce the risk of accidental exposure, oversharing, or misconfigured permissions.
- You can build good habits early: clean sources, clear ownership, audit trails, and access rules.
2) Faster adoption and less fear
Teams move quicker when the first step feels safe:
- Try AI with real company documents without “opening up the whole business” to external tools.
- Prototype workflows internally before anyone asks, “Is this compliant?” or “Where does our data go?”
- Learn what works in your context (not just generic demos).
3) Predictable costs and realistic expectations
Local testing helps you understand:
- How many prompts and tokens your workflows typically use.
- What quality you can get from smaller models (often “good enough” for operations).
- When you truly need a bigger model—or when a smaller model + good data wins.
4) Stronger outcomes from your own knowledge (RAG + clean context)
For most business tasks, the “magic” isn’t a massive model—it’s the right context:
- Your pricing rules, product docs, SOPs, and FAQs.
- Your approved language, policies, and templates.
- Your customer history and internal processes (with proper permissions).
Local RAG (document search) and graph-style knowledge can turn AI into a practical team member—without uploading your entire knowledge base to public services.
A pragmatic approach for SMEs: Local for operations - Public Ai for research
A pattern that works well:
- Local AI for anything connected to data systems like internal documents, processes, and systems (privacy + control).
- Public AI for general research, brainstorming, market summaries, or “knowledge escalation” where sensitive data isn’t involved.
This hybrid approach gives you capability quickly while keeping your “crown jewel” data protected.
Ai Servers - Ai Desktops - Ai Laptops - Ai Hosting Industrial, Automotive and Robotic AI
Security
Data Security is essential to low risk interaction and use of Ai. Start to connect to your production data or financial systems and the risks become palpable.
Control costs
Ai is not chat and when you start to train and personalise the power is clear. The true cost benefit comes from owning and controlling your own AI.
Data Hygiene
Rubbish in = Rubbish out For most rapid deployment we help you create a siloed environment. Bring data to the Ai not Ai to all your data.
24/7 protection
Ai and Robots are just high speed computers that need securing, monitoring, maintaining, supporting and managing just like any other computer.

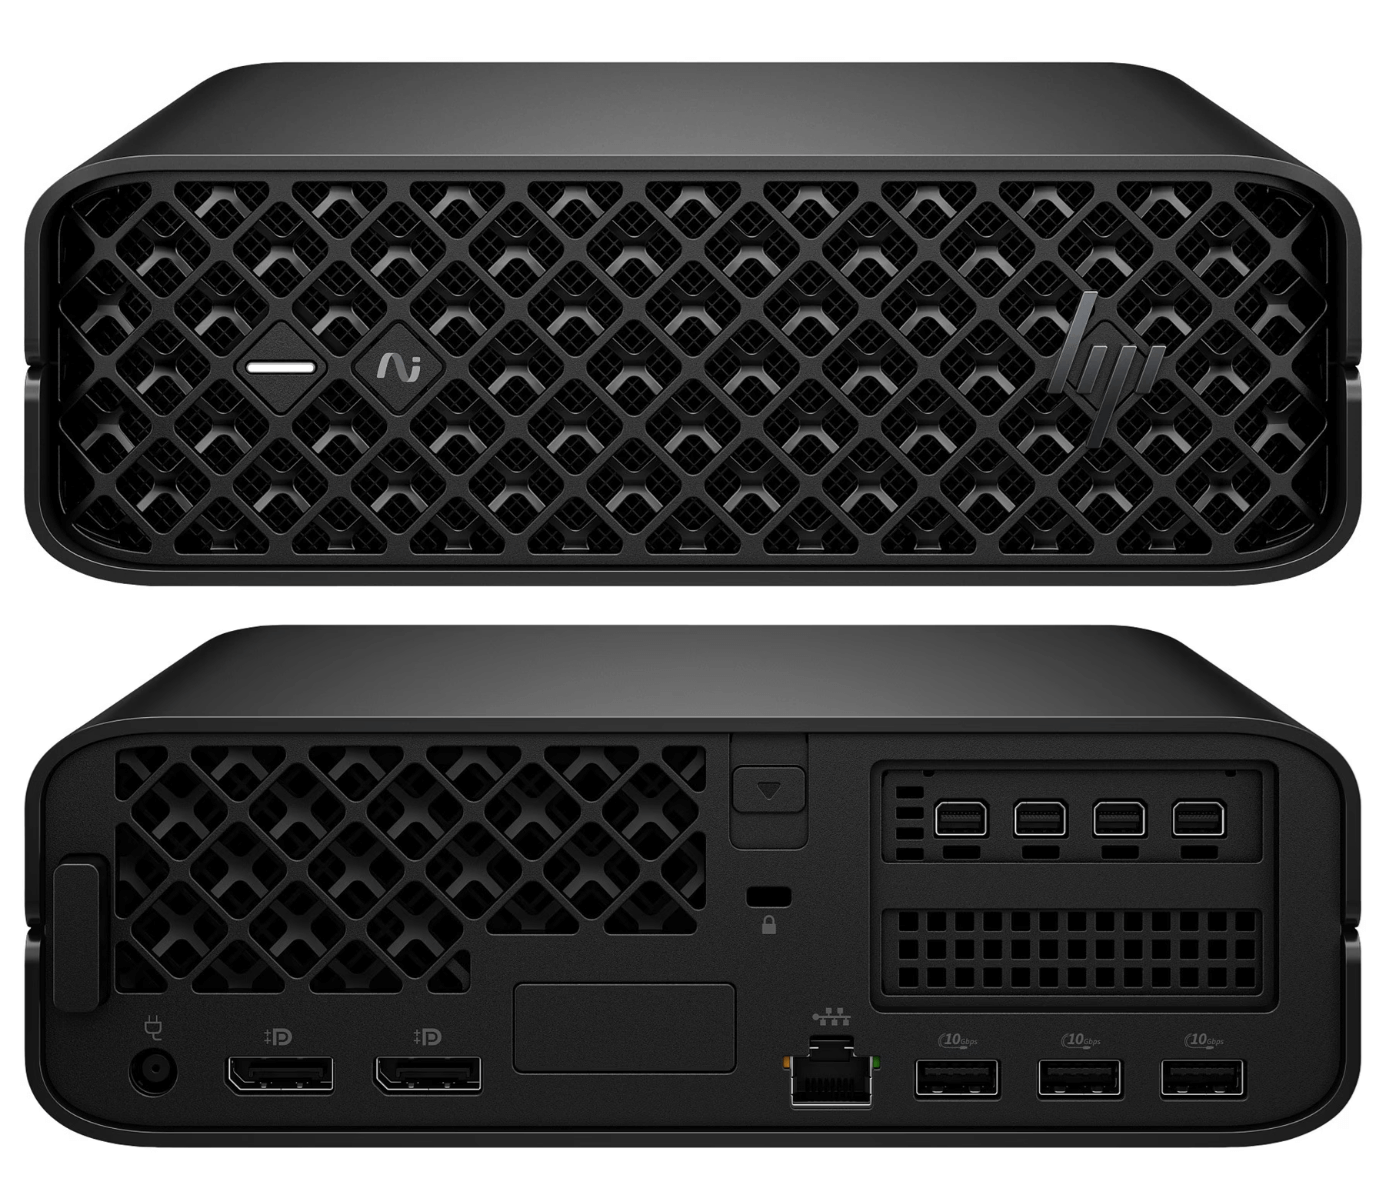
HP Z2 Mini G1a Workstation Desktop PC (AMD)
Operating system Windows 11 Pro
Processor AMD Ryzen AI MAX+ PRO 395
Memory128GB RAM
Storage2 TB SSD
Graphics AMD Radeon™ 8060S Graphics
From £2,795.99

HP Z2 Mini G1i Workstation Desktop PC
(Intel)
Operating system Windows 11 Pro
Processor Intel® Core™ Ultra 9 285K (up to 5.7 GHz with Intel® Turbo Boost Technology, 36 MB L3 cache, 24 cores, 24 threads)
Memory32 GB DDR5-6400 MT/s ECC (1 x 32 GB)
Storage1 TB SSD
Graphic NVIDIA RTX™ 4000 Ada Generation (20 GB GDDR6 dedicated)
Included HP 320K Wired Keyboard & HP Wired 320M Mouse
From £3,179.99

HP ZGX Nano G1n AI Station
(Nvidia)
Operating system NVIDIA DGX ™ OS
Processor NVIDIA® GB10 Grace Blackwell Superchip (20-core Arm, 10 Cortex-X925 and 10 Cortex-A725)
Memory128 GB RAM
Storage1 TB SSD
Graphics NVIDIA® Blackwell GPU
Architecture
(Technical Skills Recommended)
From £3,959.99

NVIDIA DGX Spark Personal AI Computer
Case
NVIDIA DGX Spark Founder's Edition: 150 mm L x 150 mm W x 50.5 mm H, 1.2 kg
CPU (Processor)
20 core Arm, 10 Cortex-X925 + 10 Cortex-A725 Arm
CPU Cooling
Integrated Thermal Management System
Memory (RAM)
128GB LPDDR5x Coherent Unified System Memory
Graphics Card (GPU)
NVIDIA GB10 Grace Blackwell Superchip
PSU (Power Supply)
240W Power Supply
Primary Storage (NVMe Drives)
4TB NVME.M2 with Self-Encryption
Wireless Networking
WiFi 7, BT 5.4 w/LE
From £3,919.99
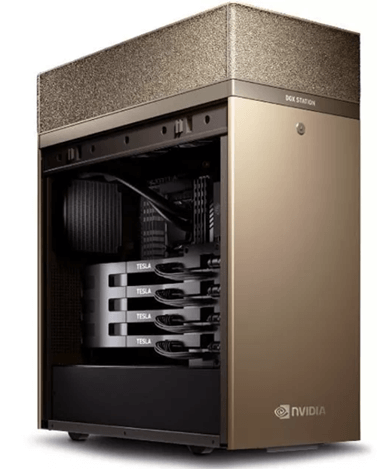
NVIDIA DGX Station * Spring 2026
The Firebox M440 incorporates the same strong security, high performance and flexible management tools that distinguish our other UTM and NGFW solutions, but this model delivers especially robust port density with twenty-five 1Gb Ethernet ports and two 10 Gb SFP+ (fiber) ports. Eight of the ports provide Power over Ethernet (PoE), which is ideal for WatchGuard Access Points.
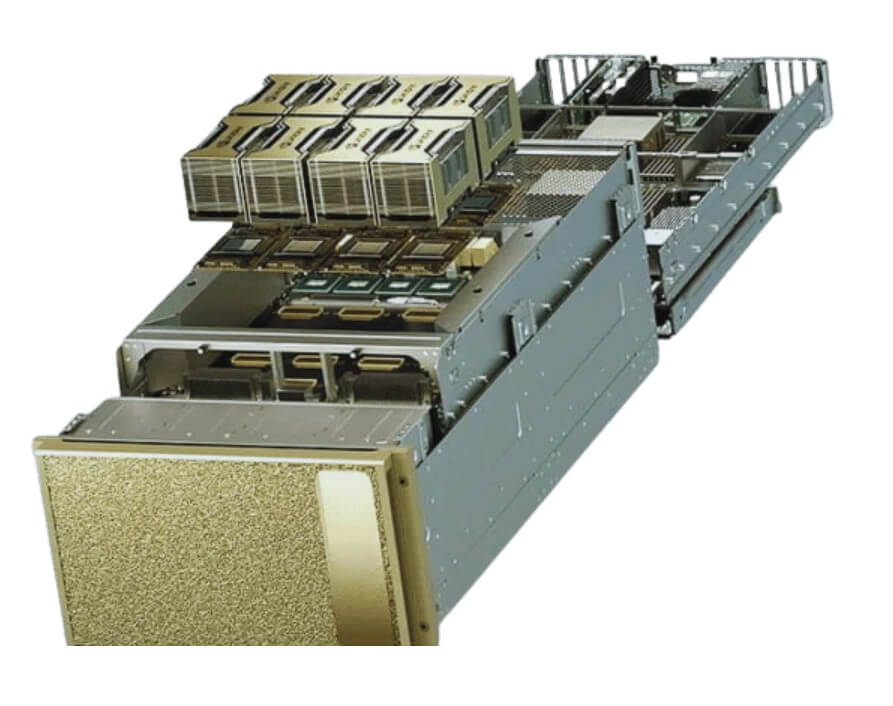
NVIDIA DGX A100
The World’s fastest single node fully integrated AI system, the DGX A100. The GPU is named AMPERE, after André-Marie Ampère, the French mathematician and physicist, considered to be the father of electrodynamics.
Crafted with 54 billion transistors, NVIDIA Ampere is the largest 7 nanometer (nm) chip ever built and features six key ground-breaking innovations.
From £180,000 - £490,000
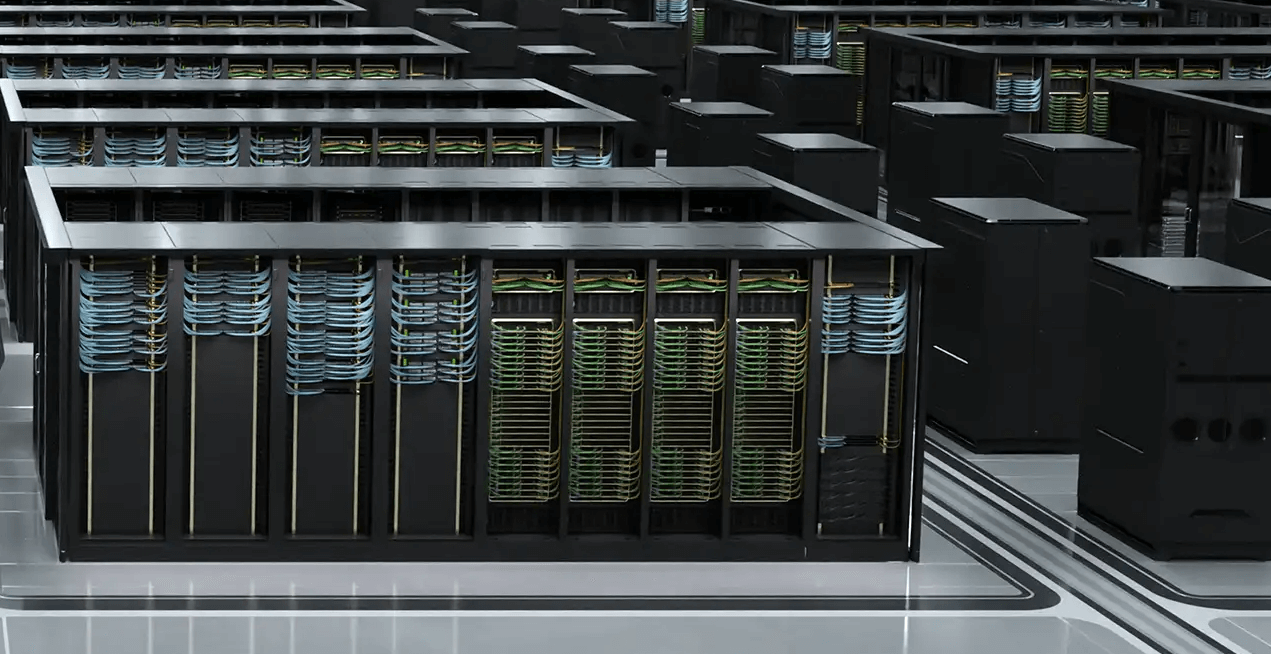
The goal at this stage isn’t perfection it’s learning:
Start small. Prove value safely. Build confidence with your data and workflows—then decide what to scale, what to keep local, and what to use public AI for.
Frequently Asked AI Questions
These FAQs provide a clear, no-fluff view of how Total Group delivers AI – with security, compliance, and scalability built in from day one.
- Local = private by design. Your data never leaves your network, reducing risk and improving compliance.
- Lower ongoing cost for heavy/continuous workloads—no per‑token or per‑API fees.
- Lower latency and more consistent performance, especially for multimodal tasks.
- Full control over models, fine‑tuning, extensions, and infrastructure.
- Cloud still makes sense for some workloads.
- Your data is not mined for profit,
- Your not building your AI house on someone else’s land which would make you incredibly sticky to using that provider.
- You can end up with 100s of disconnected agents, bots and subscriptions spread across providers, a security and personalisation nightmare.
- For 7B–13B models with solid responsiveness: 24–48 GB VRAM.
- For 30B–70B models or larger context windows: 48–96+ GB VRAM.
- CPU: 8–16 cores (or more) helps with tokenization and multimodal pipelines.
- RAM: 64–128 GB recommended for larger context and RAG workflows.
- Storage: Fast NVMe (1–2 TB+) for models, embeddings, and datasets.
- We size your desktop or cluster to your target models, context length, and concurrency.
- We pre load with a full stack Docker environment so you can start using immediately.
- Yes. Our builds support multimodal pipelines for OCR, image understanding, TTS/STT, and video frame analysis.
- We configure optimized runtimes, model acceleration, and codecs so you can run text-only or multimodal agents efficiently.
- If you need camera/mic capture or GPU video decoding, we pre‑test and enable that stack.
- So whether your a radiography department uploading Xray or an accountancy firm uploading invoices we will help you test multiple models to find the best.
- Security and compliance is our super power, clean secure data has huge functional benefits as well.
- By default, models, prompts, and data stay on your private network.
- We harden the OS, enable advanced MFA, configure SIEM/SOC/ATP (if on Microsoft 365), and set least‑privilege access.
- Secrets are managed via secure vaults; we also support encrypted at‑rest and in‑transit traffic.
- Optional CREST‑approved penetration testing is available.
- You can run hundreds of models anything that will fit on the VRAM specified. We can help you scope and Our “Ready → Steady → Go” packages covers strategy, policies, data prep (RAG), and workflow automation. Your AI working out the box.
- We build and glue real use cases—chatbots, virtual assistants, knowledge search, email triage, sales ops, and more.
- We offer ongoing optimisation, monitoring, and support so performance and accuracy improve over time.
- We are never beaten on price whether you want to use public models or local models we understand the least cost routes to implement We tell you the secrets AI companies don’t want you to know to keep costs down.
- Typical one‑off setup from £2,577 + from £200/month for a secure, compliant foundation.
- Development/automation cycles from £4,125 per cycle for your first few bots and agents you build but Vibe coding is becoming very capable.
- The cost of local compute and coding is plummeting, invested now to leverage this quickly.
- Scaling: from £1,500 one‑off + from £425/month per device; we can add local GPUs, clusters, or hosted GPUs as you grow.
- We’ll tailor a quote based on your models, concurrency, and compliance needs.
- Absolutely. We have the most flexible approach to change and scale:
- More powerful single workstations or multi‑GPU desktops.
- Small on‑prem clusters for 70B+ parameter models or higher throughput.
- Private hosted GPUs (e.g., Azure ND A100/H100 series) with containerized deployments.
- Hybrid routing: keep private data local while burst‑scaling public workloads.
- We handle orchestration, load balancing, backups, and monitoring across devices.
- We can migrate on premise data and workflows to the cloud and back with ease.
- Keep control of your knowledge: With local RAG (Retrieval‑Augmented Generation), your documents, embeddings, and context stay on your own infrastructure—improving privacy, compliance, and auditability.
- Better accuracy with less fine‑tuning: RAG injects the right context at query time, so you get grounded, source‑linked answers without expensive end‑to‑end model fine‑tuning.
- Portable data, flexible models: Because your vector databases and embeddings are yours, you can point multiple local models at the same knowledge base and swap models over time without “re‑training your company” into a single vendor’s stack.
- Avoid vendor lock‑in: If you build directly inside a public model/provider, your “training” often isn’t portable. With local RAG, your data, schema, and pipelines are transferable—on‑prem, hosted GPUs, or hybrid.
- Lower costs for updates: Updating content is as simple as re‑ingesting and re‑embedding new documents—no costly model retrains required.
- Traceability and governance: You can log sources cited, control retention, and enforce access policies at the document and field level.
For general questions, visit our Contact FAQ.
